In February 2024, I sat in a pipeline review and watched the numbers flash on the screen. 3,004 leads. 1,800 emails sent. 218 bounced. 34 replies. 7 demos. 2 sales-qualified leads.
Two. That’s the number I had to explain to our VP of Sales. We had spent six weeks building what I called the prospecting machine. It used Lindy AI, a business email finder, enrichment data, everything. And it still produced almost nothing.
This isn’t a story about AI being overhyped. The AI did exactly what I asked. The problem was the step I didn’t ask for.
I Thought the AI Would Solve the Data Problem
When I first started building with Lindy AI, I assumed the AI would somehow know which contacts were real. I’d read the lindy ai official website features page and saw the core pieces: AI agents, email automation, LinkedIn outreach, CRM sync. It sounded like a full SDR team in a box.
We connected a business email finder to the workflow. That was the data layer, or so I thought. I remember looking at a sample output and thinking, “If the email field is filled in, we’re done.” That was the initial misjudgment.
Look, I’m not saying the lindy ai tool didn’t work. It worked exactly as configured. The problem was my configuration.
What the Workflow Actually Did
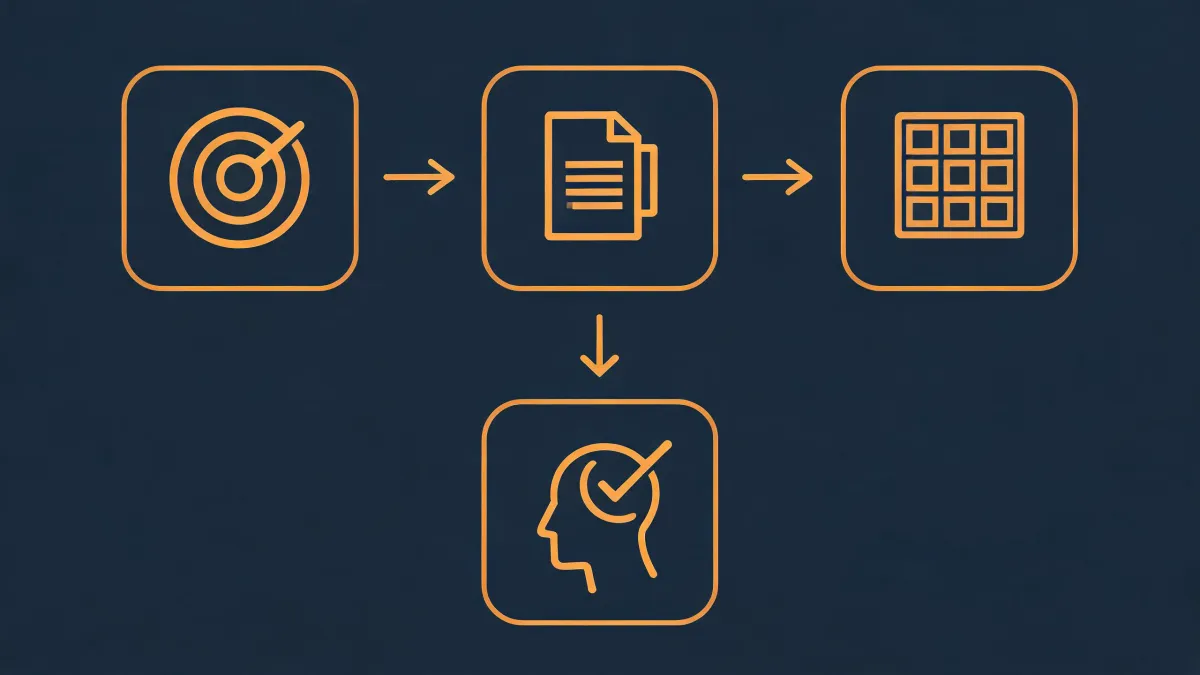
Here’s what our agent-native workflow looked like at the time:
- Find accounts that matched our ICP.
- Locate the decision maker.
- Use the business email finder to pull an email address.
- Enrich the record with phone, LinkedIn, and notes.
- Push the list to the sales team.
No verification step. That was the gap.
We didn’t have a formal email validation process. I thought it was an extra cost for people who bought scraped lists. But we were basically doing the same thing: collecting addresses and hoping they were live.
The first red flag came when a rep complained that a quarter of the emails in her first batch bounced. She said it like it was a normal day. That scared me more than a formal complaint would have.
The Right Place for Email Validation
The honest question I should have asked in January was how does email validator fit into an agent-native prospecting workflow. The answer, after rebuilding the process, is simple: it belongs right between enrichment and outreach.
The agent finds a prospect, enriches the record, verifies the email, and only then adds the person to the active outreach list. If the email fails validation, the agent can either find a better address or mark the record as unqualified. That decision alone changes the list from “people we think exist” to “people we can actually contact.”
What I mean by the word “qualify” is also worth explaining. For us, a sales-qualified lead is someone who fits the ICP, has budget authority, and is actually responding. The email validator doesn’t decide whether a lead is qualified. It just makes sure the conversation has a chance to start.
Certainty Is Worth the Extra Fee
I used to think email validation was a waste of money. The finder already gave me an email. Why pay someone to tell me what I already had?
Here’s the thing: an email validator doesn’t just check syntax. It checks whether the domain has a mail server, whether the address is likely to receive messages, and whether the record shows risky patterns. It fails fast on bad data so your reps don’t waste a week on contacts who will never see the email.
In our case, the cost of not validating was way higher than the fee. The bad batch cost us about 120 hours of rep time, two weeks of delayed follow-up on the leads that were actually good, and a lot of trust from the sales team. The validator plan we added was about $99 a month. The lost time was closer to $6,000.
I’m not saying every tool with a high price is worth it. But when a workflow is agent-native, the whole point is that the agent handles the boring steps consistently. Email validation is one of those boring steps. Skipping it doesn’t save money; it moves the risk and the cost to your highest-paid people.
What Happened After We Added Validation
We rebuilt the workflow. I added a step between enrichment and outreach: verify the email address. If the address failed, the agent tried a secondary source. If the second source also failed, the record was marked “to re-research” instead of being pushed to reps.
Here’s what changed over the next month:
- Bounce rate: 12.1% down to 2.3%.
- Reply rate: 1.9% up to 6.4%.
- Sales-qualified leads per week: 2 up to 9.
Some of that improvement came from better targeting. But the email validator was the reason a good number of those messages landed in a real inbox at all.
To be clear, no email validator catches everything. People change jobs, servers change settings, and sometimes a valid-looking email still bounces. Lindy’s docs don’t claim a 100% validation rate, and neither do I. It’s not about perfection. It’s about removing the avoidable mistakes so your team can focus on the contacts who are actually reachable.
What I’d Do Differently
If you’re building an agent-native prospecting workflow, put the email validator in before any rep sees a list. Treat it as a quality gate, not an upsell.
Three things I’d tell my past self:
- An email finder doesn’t validate. It finds.
- A sales-qualified lead starts with a deliverable email.
- Paying for certainty is not a luxury. It’s how you protect your team’s attention.
We now run every list through validation before it reaches the CRM. It’s the most boring step in the workflow, and it’s the one I’d never remove.
Because in the end, the money we spent on validation bought certainty. Certainty that our reps weren’t talking to ghosts. Certainty that the pipeline review numbers were real. That’s worth paying for.